Layer 04 · Product
MangaReader
A manga reader that scrapes chapters from third-party sites, merges them into series, and serves them through a web interface.
What it does
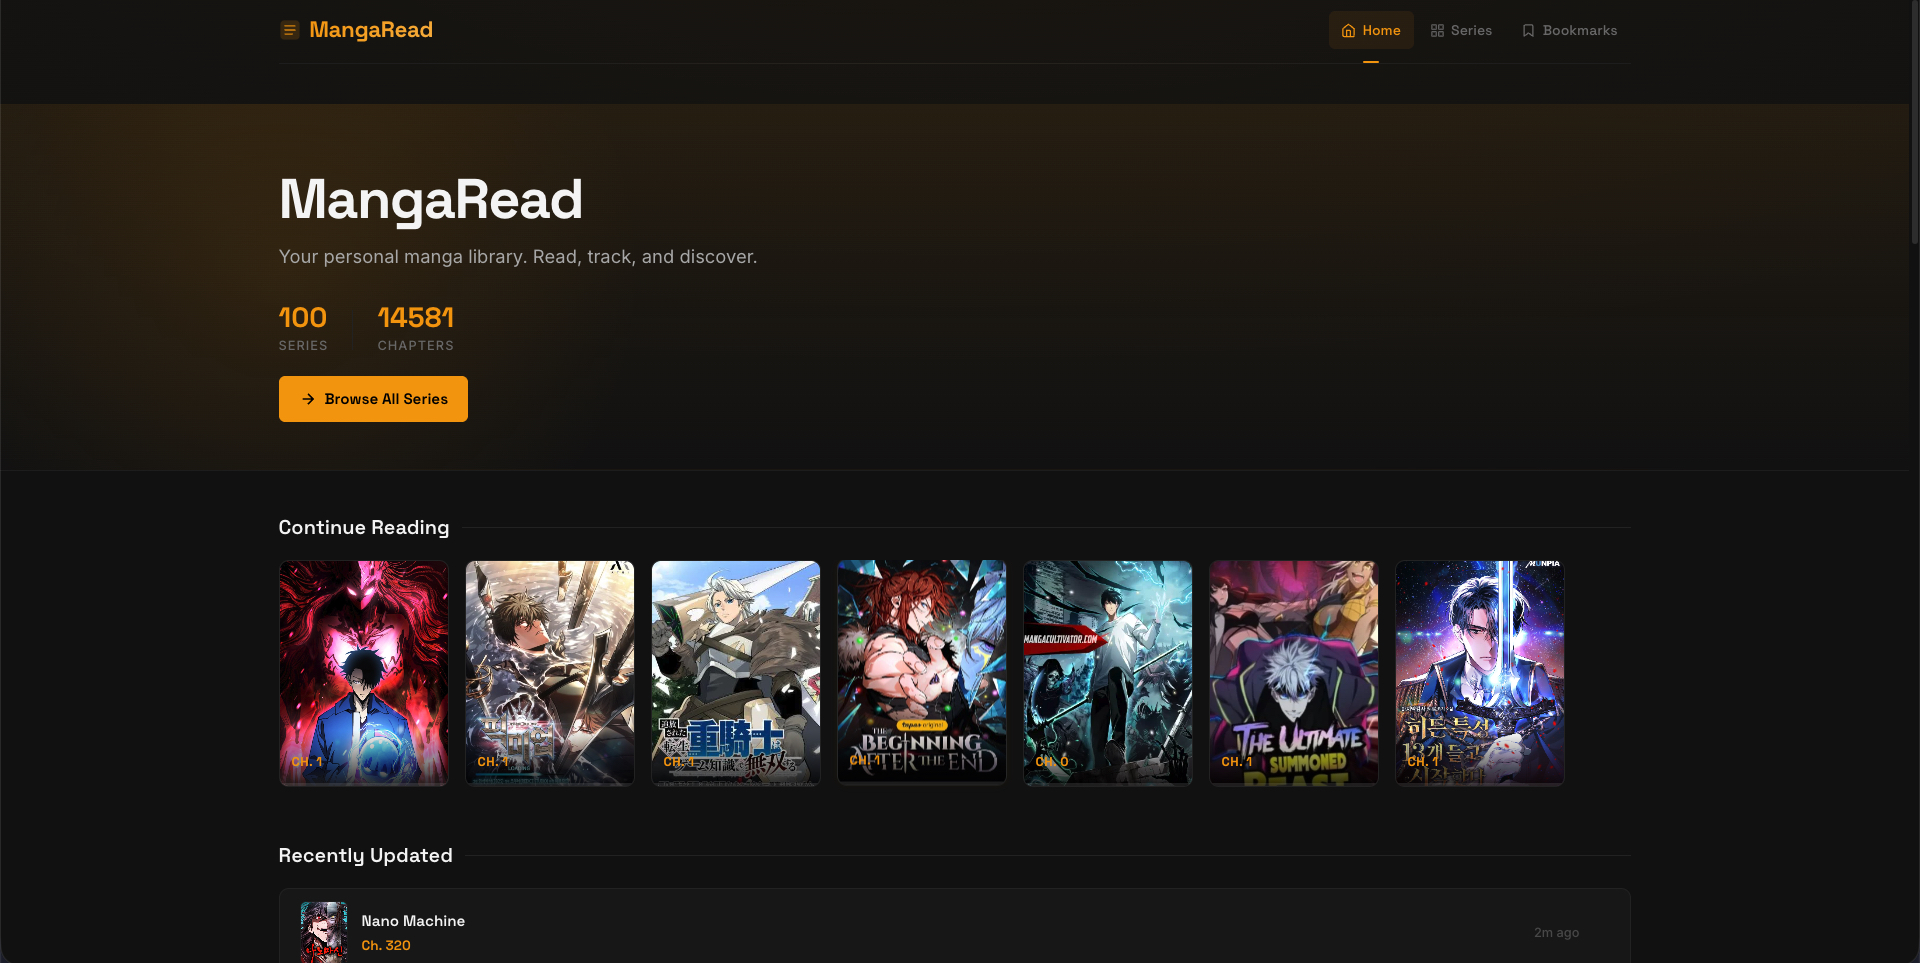
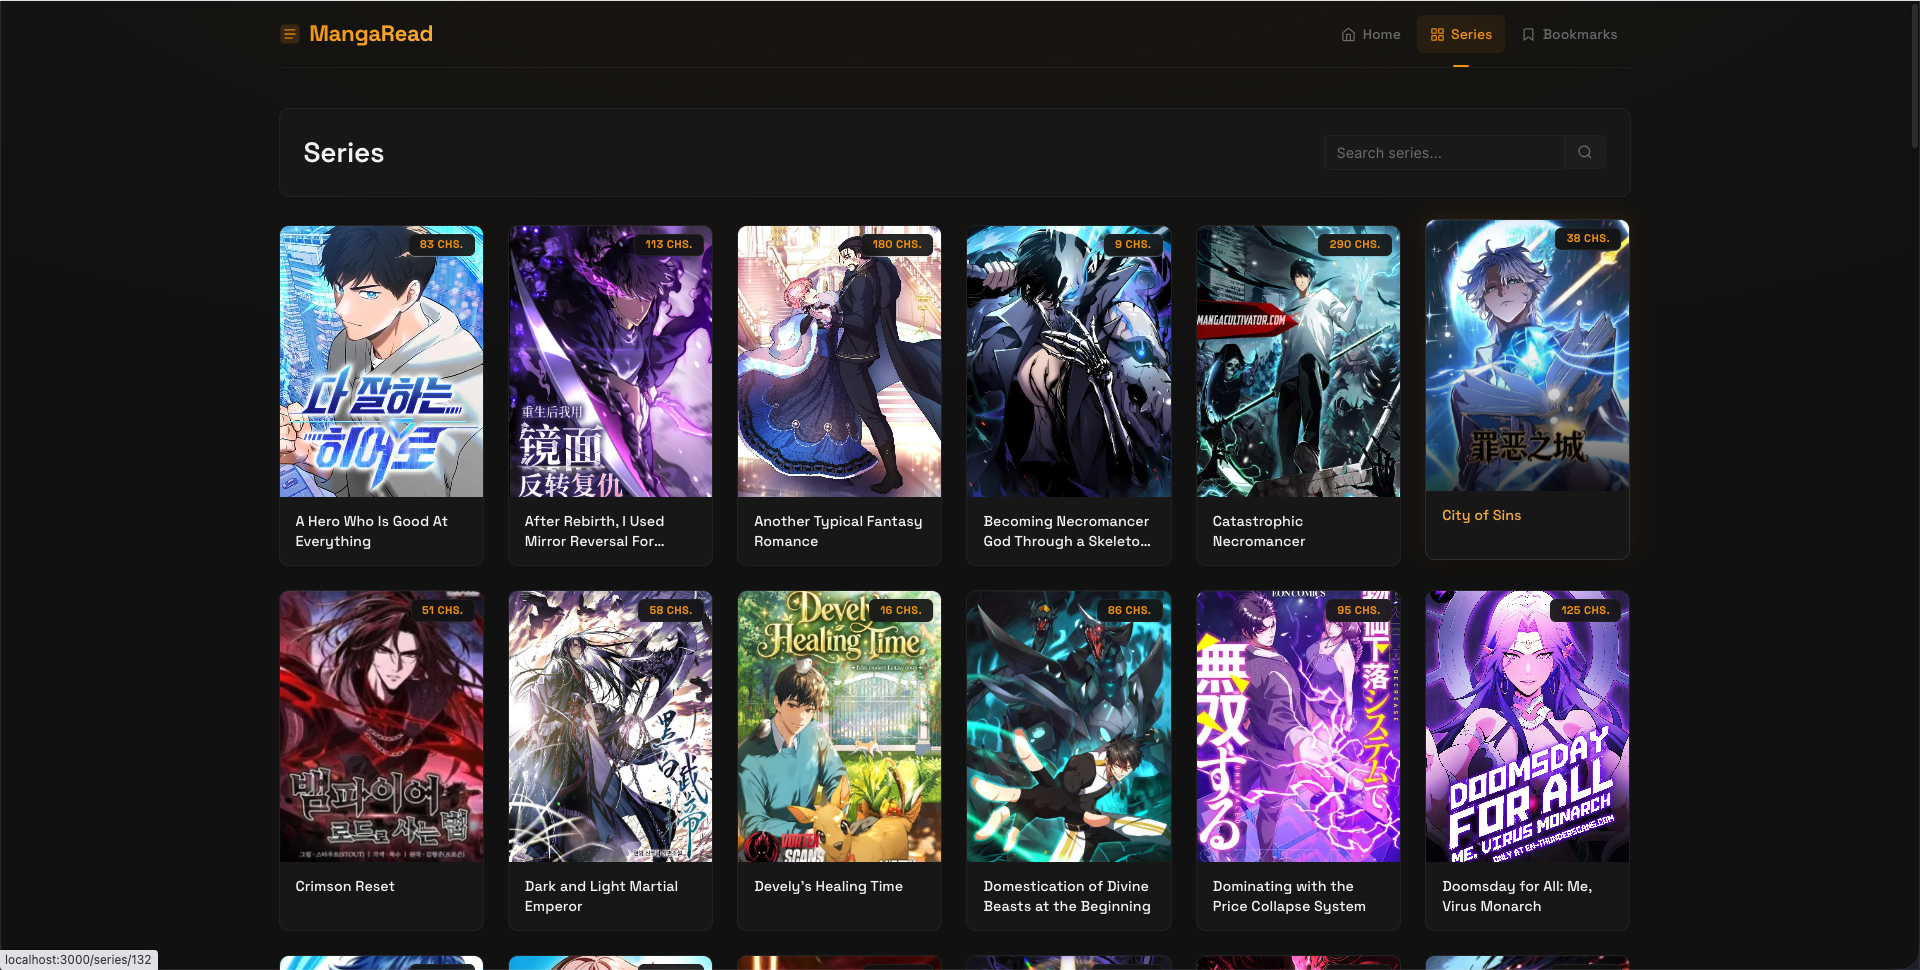
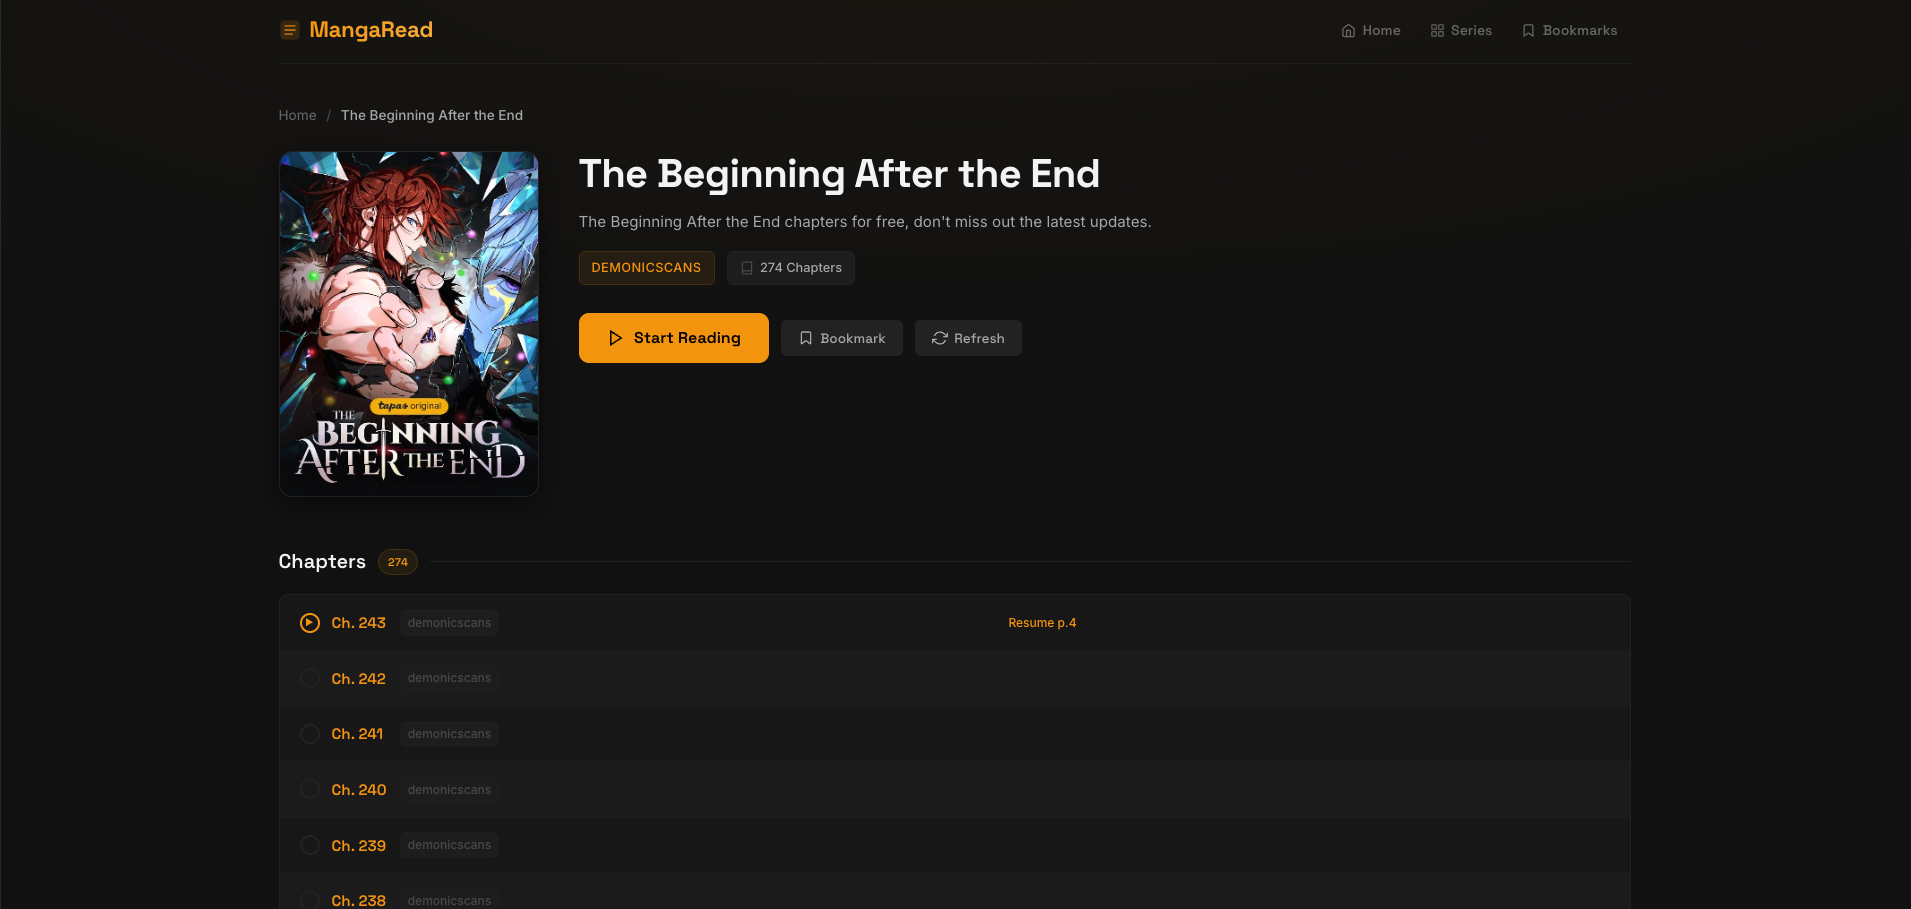
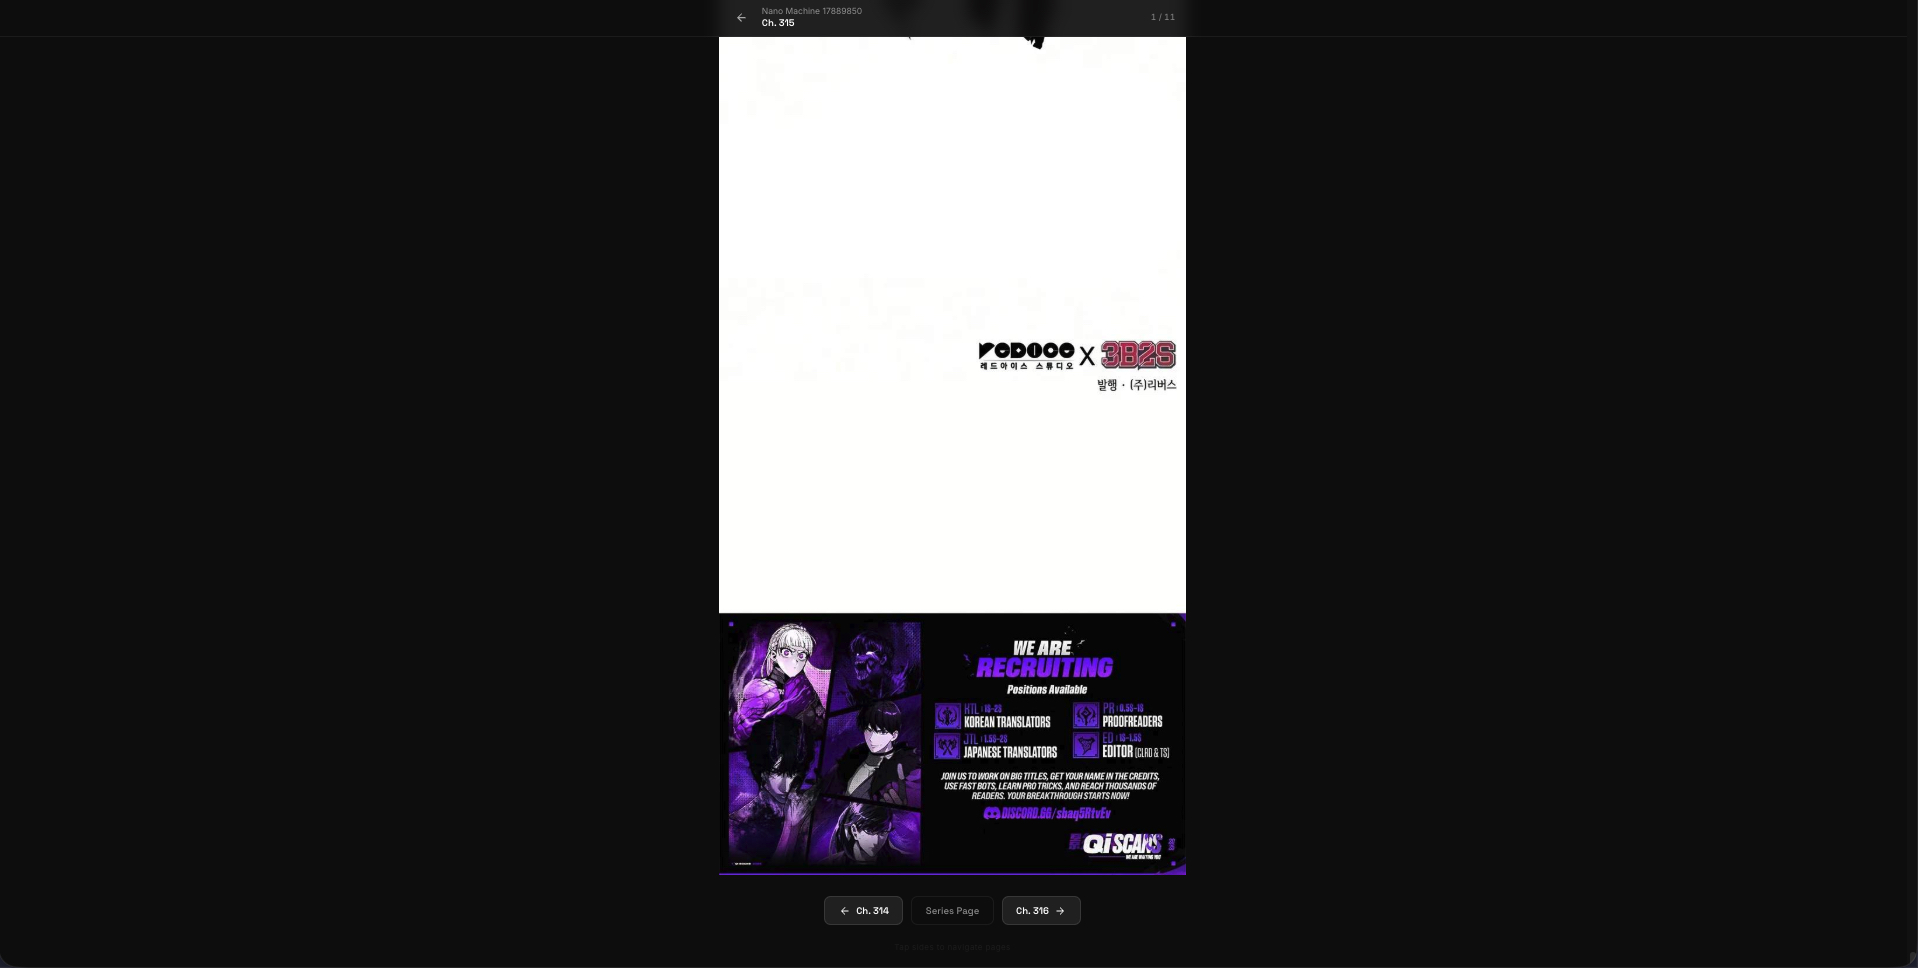
MangaReader is a self-hosted manga library. It fetches chapters from third-party sites, merges the same title into one series, and serves a reader with accounts, bookmarks and synced progress. New chapters sync in the background.
Architecture
Three Rust crates in one workspace:
- mangaread-core: domain types, SQLite repository, series merging logic
- scraper: SiteAdapter trait with per-site implementations (Demonicscans, Manhuaplus), CLI binary + library
- website: Axum web server with Maud templates, accounts, an admin area and static assets
The database uses SQLite in WAL mode, in a single file.
Series from different sources are merged by normalized title.
flowchart TB
    CLI[ScraperEngine] --> DB[(SQLite)]
    WEB[Axum Server] --> DB
    WEB <--> BROWSER[Browser]
Accounts are optional. Visitors can read without signing in, and their progress stays in the browser. Signed-in readers get progress, bookmarks and notes synced across devices.
Screenshots
The hard parts
Chromedriver. The scraper uses a real browser for JavaScript-heavy manga sites. Getting chromedriver to behave in Docker was 30% of the dev time. Headless mode bugs, sandbox issues, zombie processes: the usual webdriver circus.
SQLite and threading. rusqlite's Connection isn't Sync, so each scraper thread opens its own connection. The main AppState wraps its own in a Mutex. Sounds simple, but the borrow checker had opinions.
Fighting the borrow checker for the 50th time at 2am is a rite of passage.
What I learned
Splitting this Rust project into workspace crates taught me more than any tutorial. Rust's type system is genuinely great for domain modeling (no invalid states possible), but fighting the borrow checker for the 50th time at 2am is a rite of passage.
The scraper adapter pattern (trait + per-site implementations) paid off immediately when adding a second source. And the sync loop (background thread, 6-hour interval, parallel scraping) taught me about Tokio channels and graceful shutdown the hard way.
Also: always pin your chromedriver version. Always.